

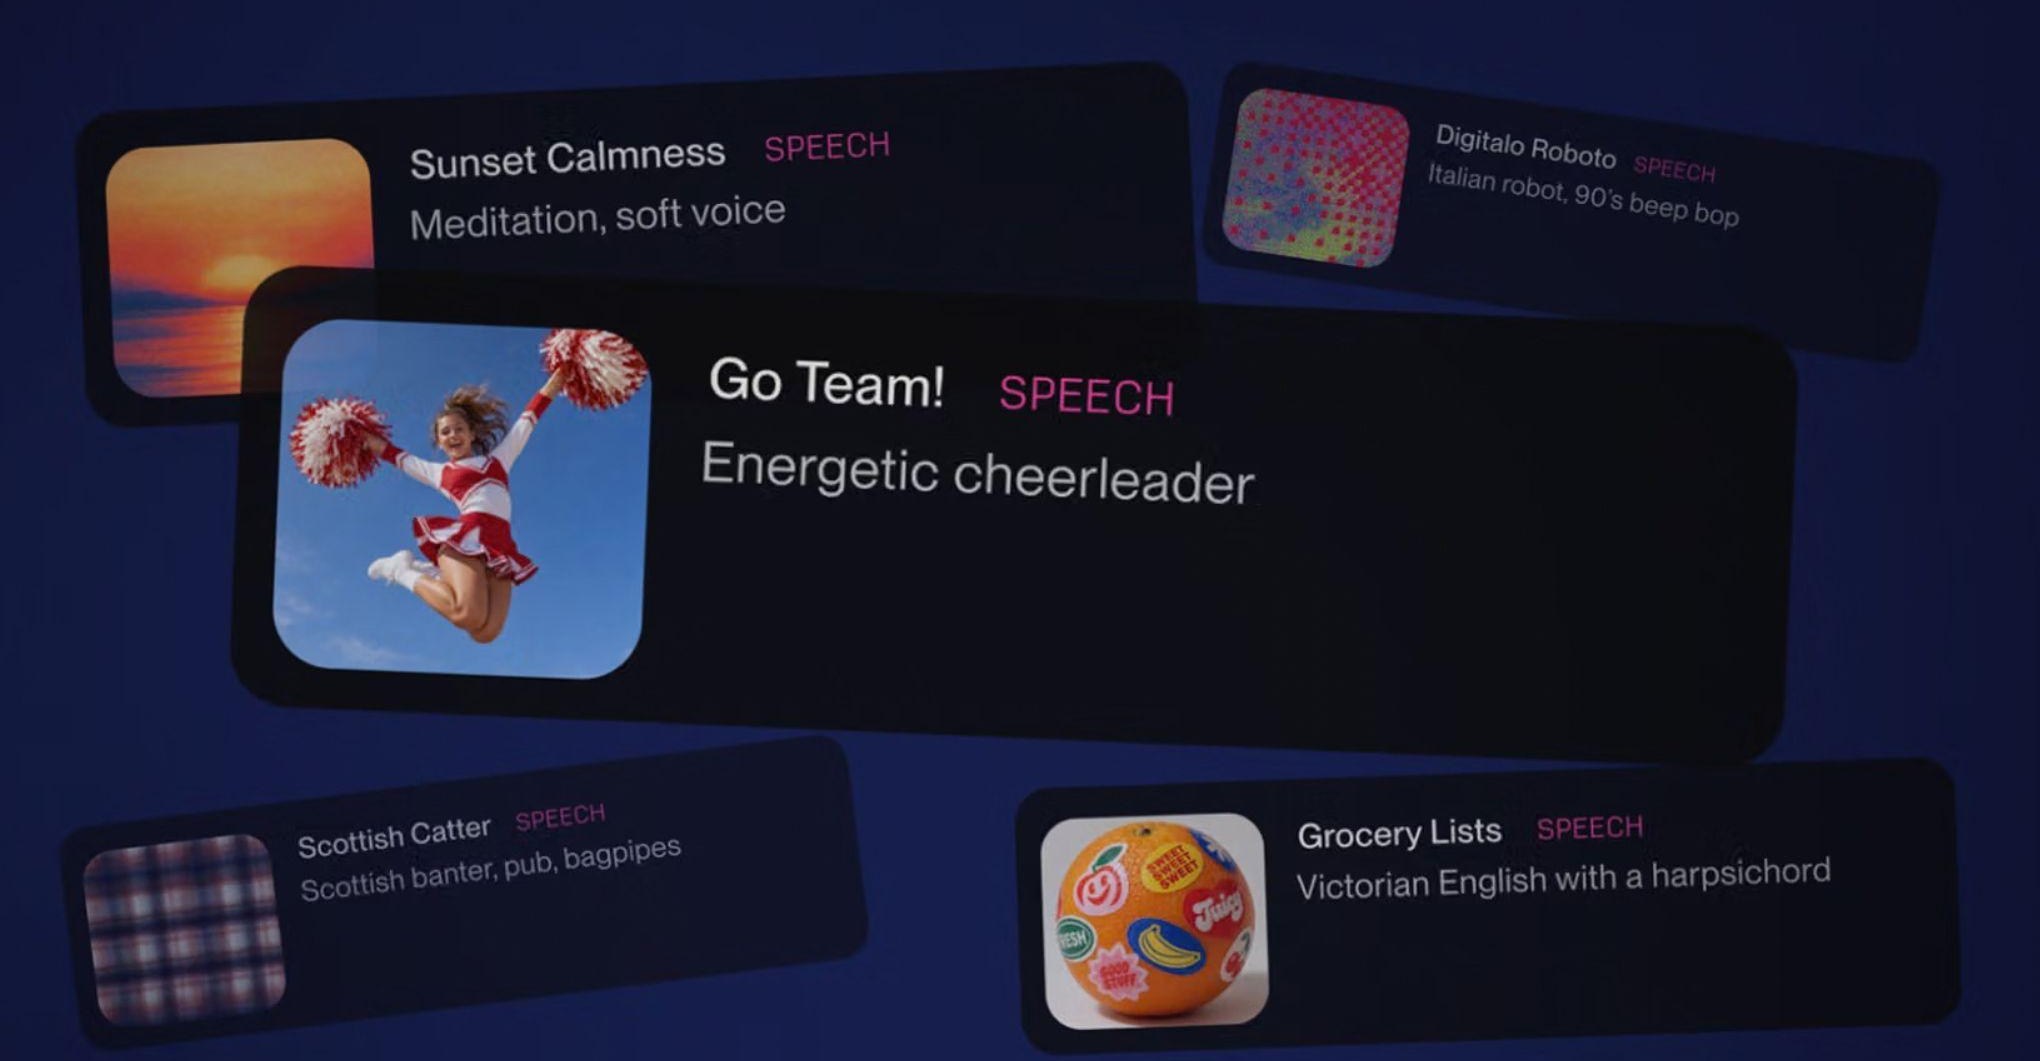
Suno has launched Speech, a public beta feature that generates spoken audio from a script or a written description. It is available on Suno’s web and mobile platforms and can generate a voiceover alongside background music in one track.
The music is optional and can be turned off. Suno presents the feature as a way to pair speech with suitable soundtracks, such as calming music for poems or more energetic backing for dramatic voiceovers and encouraging speeches.
Users can find Speech under the Create tab. Simple mode generates audio from a description, while Advanced mode accepts a custom script. Advanced settings also let users adjust the voice’s gender and speaking style, and how much variation a generation includes. Speech can last up to around eight minutes.
Suno chief product officer Jack Brody described Speech as the company’s first audio model to generate voice and music together. AI speech generation is already offered by other companies: DeepMind has worked on speech synthesis for a decade, Adobe has a text-to-speech tool, and ElevenLabs launched in 2023.
Suno says Speech is still being improved using user feedback. Brody acknowledged that beta outputs can have inconsistent accents and overly dramatic pauses. The Verge reports that Suno’s music generator has attracted lawsuits; the announcement does not state that Speech is a response to them.
Comments
0No comments yet. Be the first to comment.