

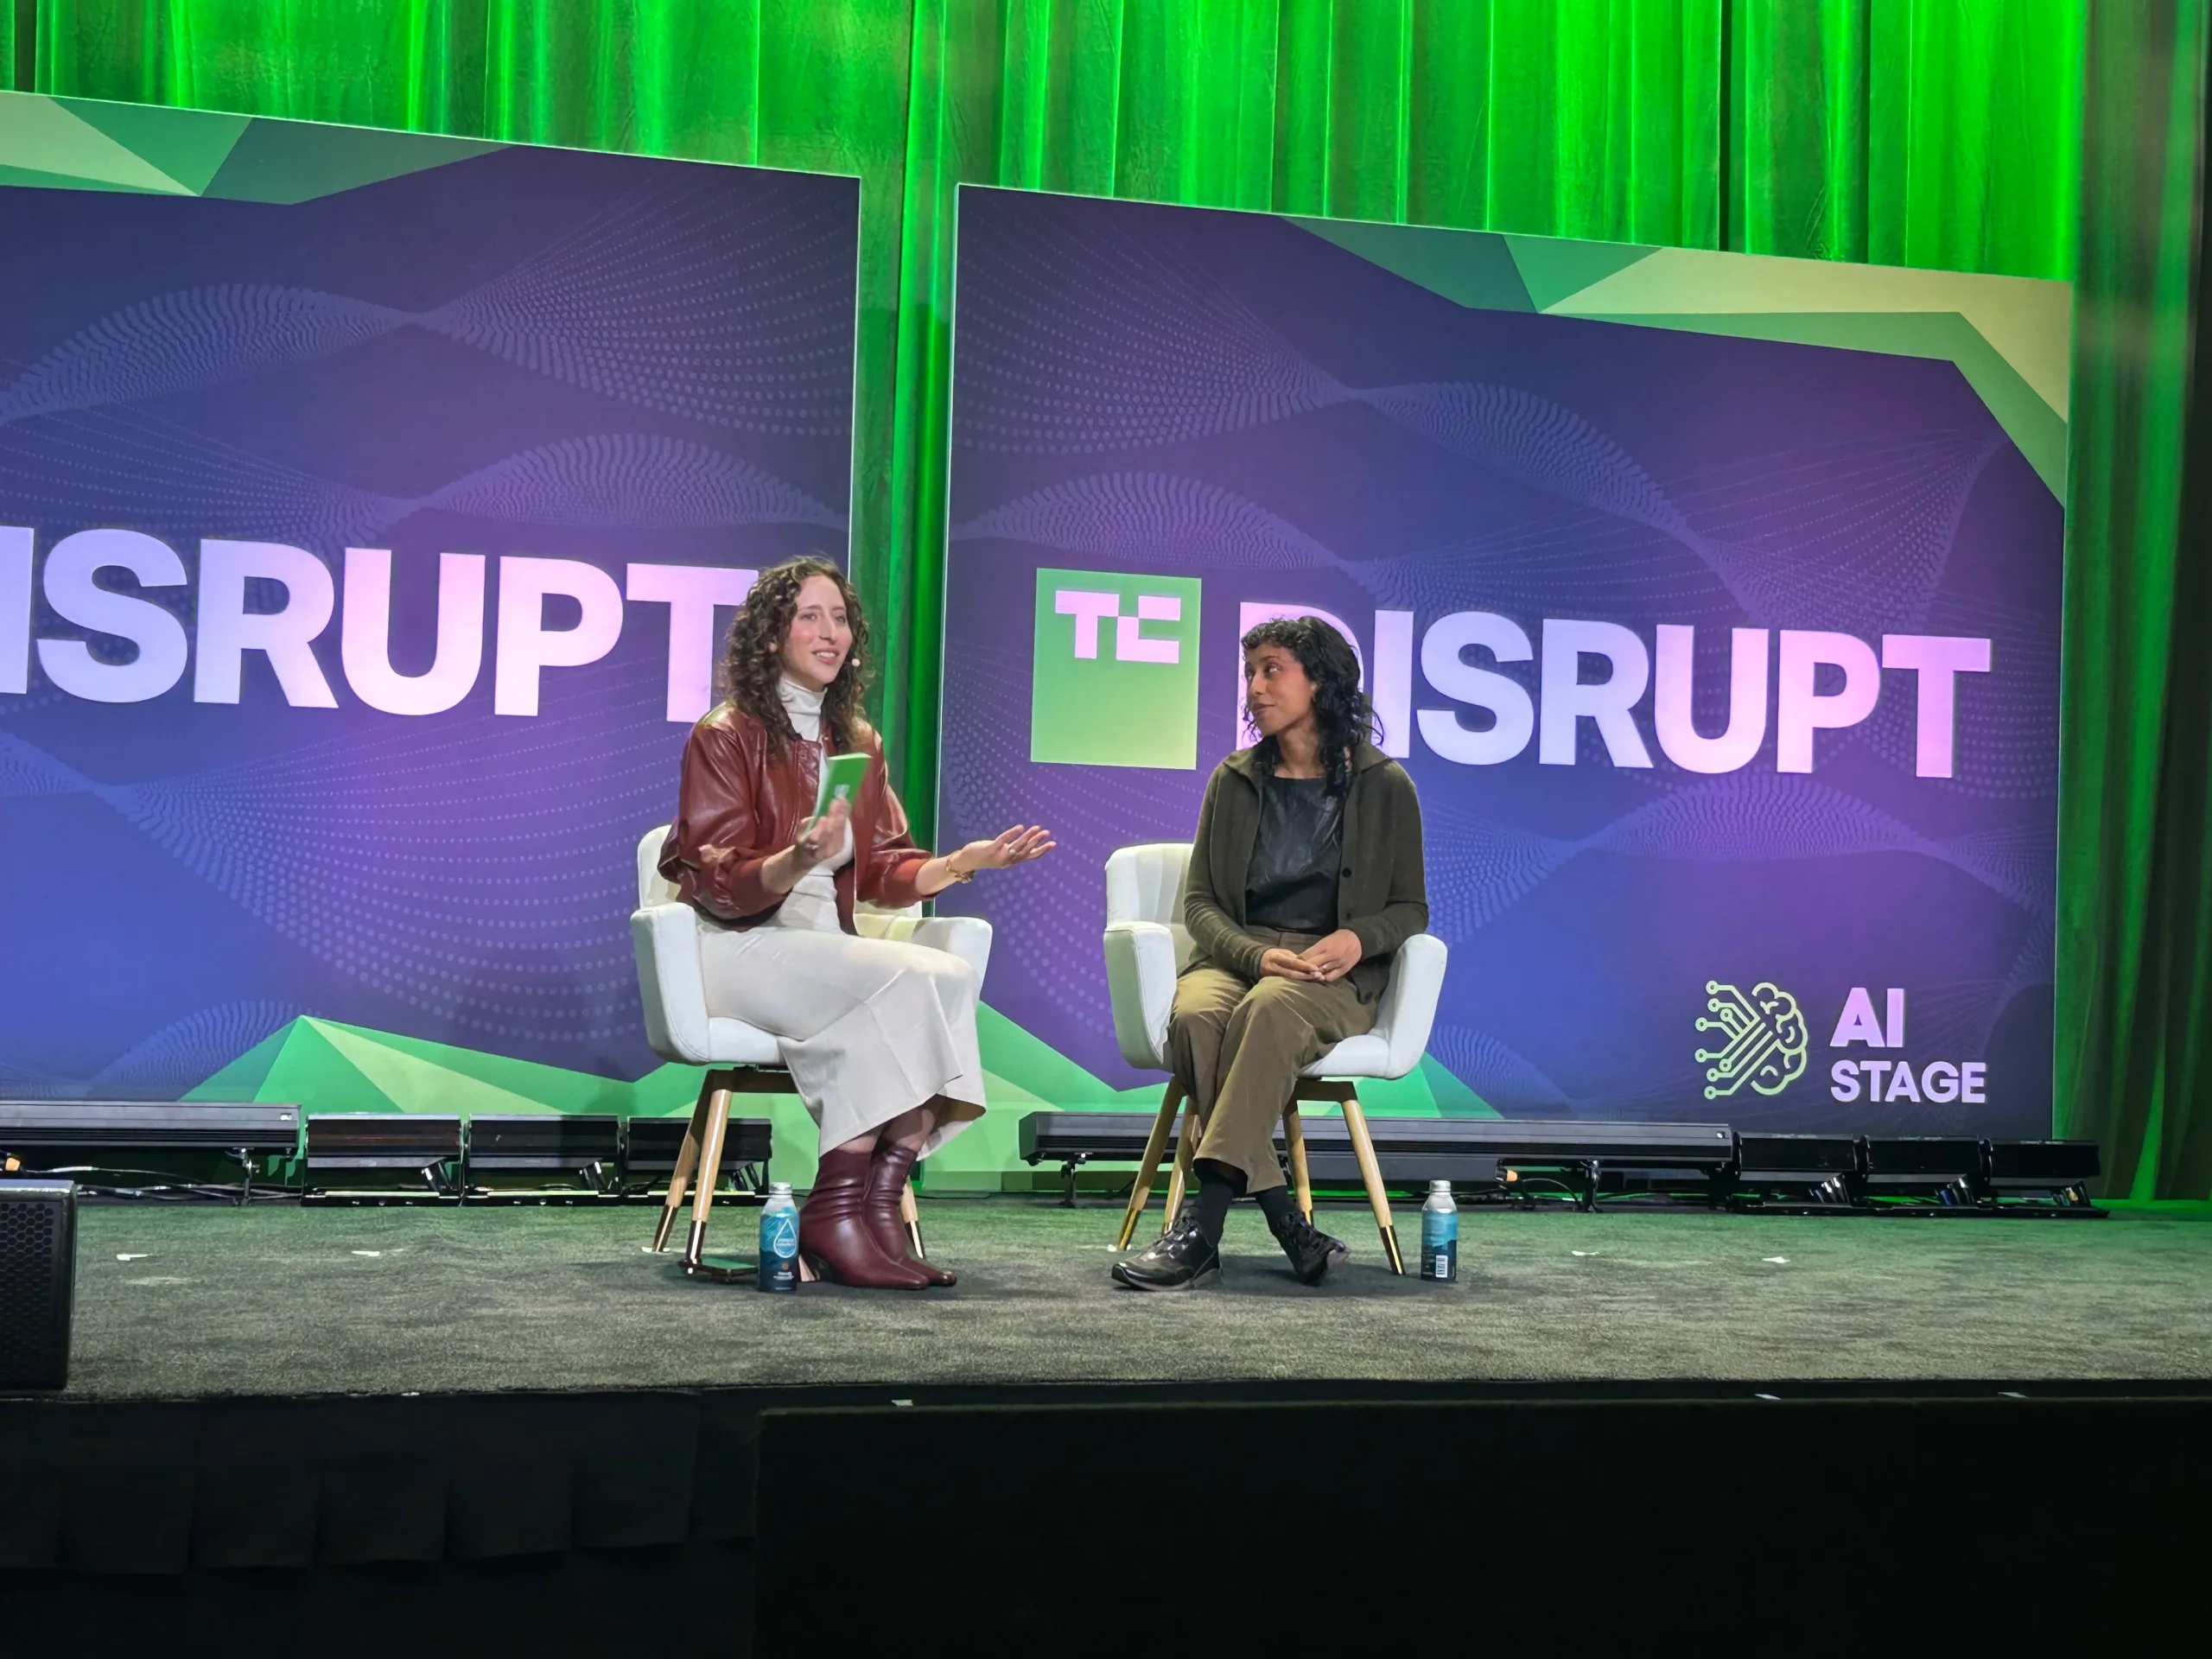
AI companies rely on benchmarks to compare models, but the methods behind those tests remain complicated and are still developing, said Irene Solaiman, Hugging Face’s chief policy officer, at TechCrunch Disrupt last week.
Solaiman said confidence in evaluation results depends in part on whether others can reproduce them and have enough access to the model. She pointed to open weights as one way to support that access. She also said evaluations are hard to compare with one another, can become ineffective quickly, and need more standardization.
The discussion comes as AI labs face scrutiny after safety incidents and promote embedded evaluators: supposedly neutral third-party observers placed inside AI organizations. Solaiman said the qualifications for evaluators across different tasks need clearer standards. Anthropic’s choice of Accenture as its first evaluator drew criticism from people who questioned the firm’s qualifications.
Evaluations are also expanding beyond models to include the systems around them, such as the harness users rely on and AI agents. Solaiman said a better harness can help a weaker model outperform a frontier model. She described agent evaluations as difficult and expensive, and said evaluations for harnesses remain less developed than model evaluations. She said work is underway on broader evaluations of whole agents.
Comments
0No comments yet. Be the first to comment.