

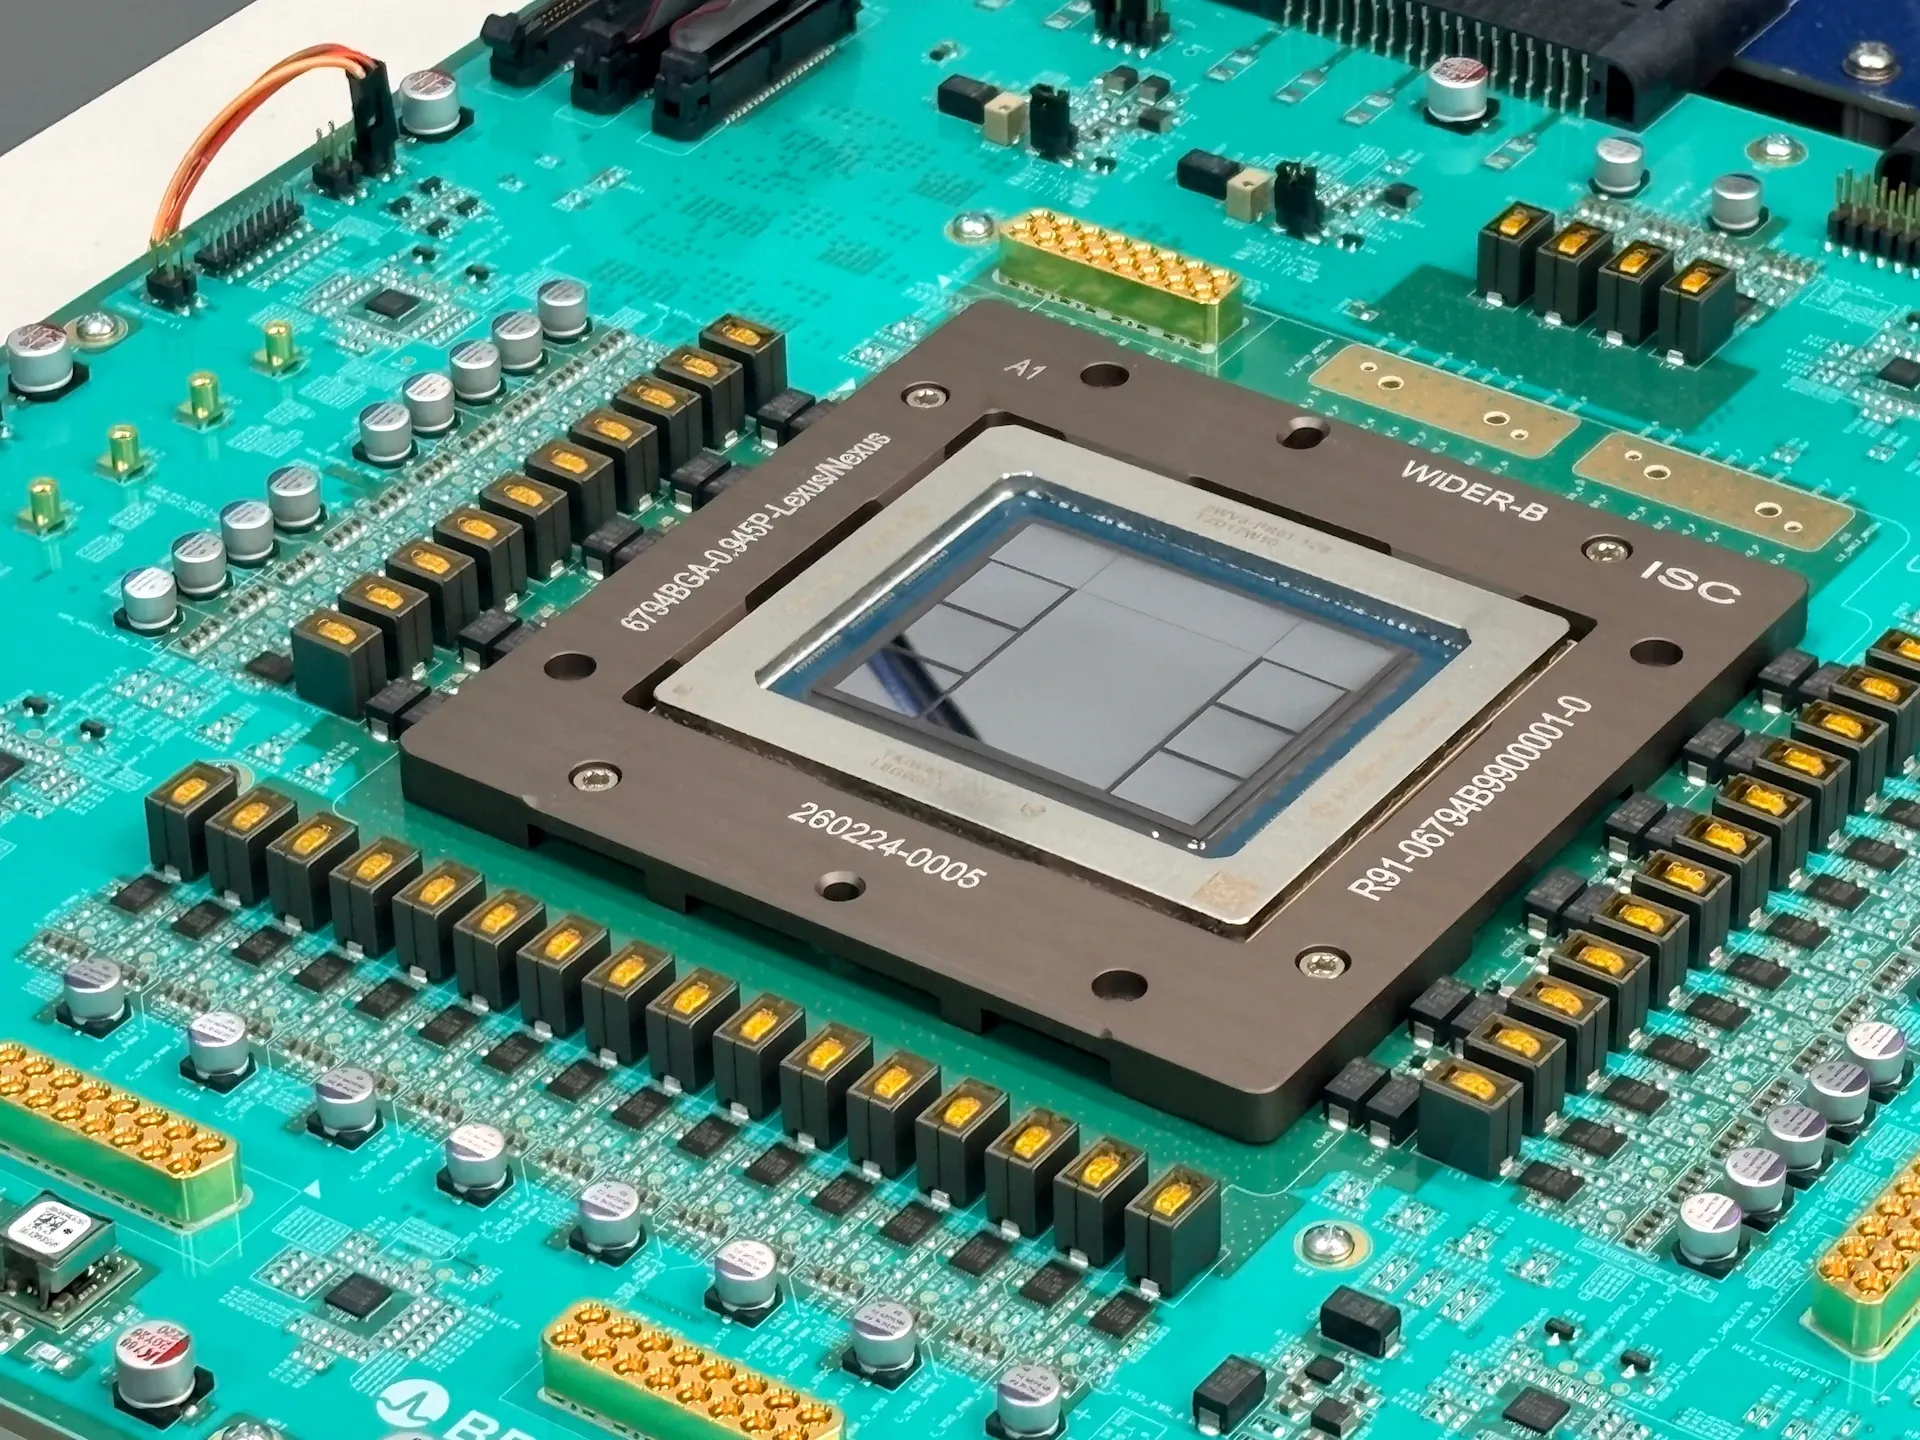
OpenAI has published its first performance figures for Jalapeño, an inference accelerator co-developed with Broadcom. The company presented the results at Hot Chips on August 25, focusing on efficiency rather than a direct comparison with Nvidia’s Vera Rubin architecture.
Across three open models, OpenAI reported 1.5 to 1.9 times more throughput per kilowatt and 1.7 to 3.6 times lower end-to-end latency than the Nvidia rack systems it tested. Jalapeño is rated at 700W, compared with 1200W and 1400W for the Nvidia systems.
OpenAI tested SemiAnalysis’s public InferenceX suite with GPT-OSS 120B, DeepSeek R1 670B, and Moonshot AI’s trillion-parameter Kimi K2.5. It reported a 1.9x efficiency advantage over GB200 on GPT-OSS, and 1.7x and 1.5x advantages over GB300 on the other two models. A GPT-OSS 120B comparison between Jalapeño and GB300 was not published.
The figures use single-token prediction, without speculative decoding or prefill-decode disaggregation. In a multi-token configuration, Jalapeño’s peak efficiency lead over GB300 falls to roughly 1.5x. The tests use A0 silicon, while a B0 stepping with roughly 25 percent better performance per watt is already in fabrication. Production is scheduled to ramp gradually across 2027.
Comments
0No comments yet. Be the first to comment.